A model can become very good at understanding instructions without knowing how authority works inside your organisation.
It does not automatically know that someone in accounts may view one set of customer information but not another.
It does not know that a sales manager can propose a discount but only a director can approve one above a certain threshold.
It does not inherently know which version of a document is authoritative, whether personal information may leave a particular environment, or whether changing a production system requires a second person to sign off.
Those are business rules. They belong to the organisation, not the model.
OpenAI has made progress here at model level. Its Astra safety evaluations include realistic workplace environments involving email, messaging, browsing, project management and sales systems. The model is trained to exercise care around consequential actions, and explicit confirmation policies further reduce unintended outcomes in those tests.
That is useful progress. But a confirmation policy only works when somebody has first defined what requires confirmation.
That is the enterprise AI governance problem.
Start with identity, not the model
When I look at enterprise AI security, I would start with a fairly ordinary IT question: who is asking?
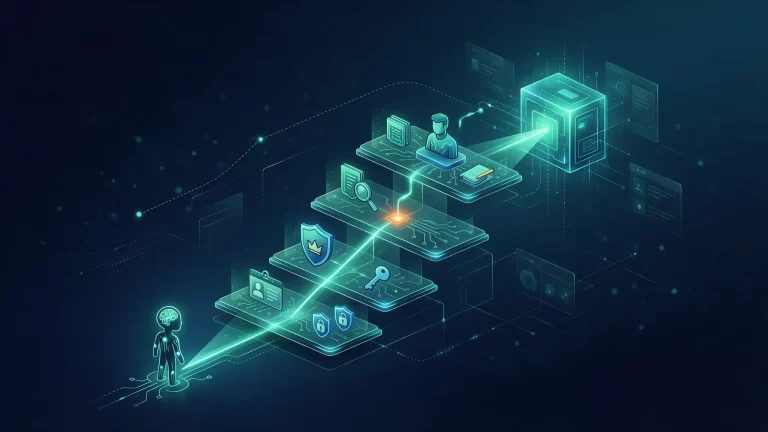
Before an AI system retrieves company information or performs an action, it should understand the identity and permissions of the person making the request.
If Jane cannot open the finance folder herself, asking an AI assistant to summarise that folder should not become a way around the restriction. If Peter has access to the UK customer database but not the South African one, the AI should inherit that boundary.
This sounds obvious, because businesses have spent years building access controls around applications, files and databases. AI cannot become the exception.
The useful way to think about an enterprise AI assistant is not as an all-knowing layer sitting above your systems. It should operate within the same authority structure as the person using it.
That means authentication, roles, permissions and data boundaries matter before the prompt reaches the model.
Control the information the AI receives
The next question is what information a request is allowed to use.
Enterprise AI becomes far more useful when it can work with real company information: customer records, contracts, internal policies, product documentation, financial data, support tickets, project information, operational systems.
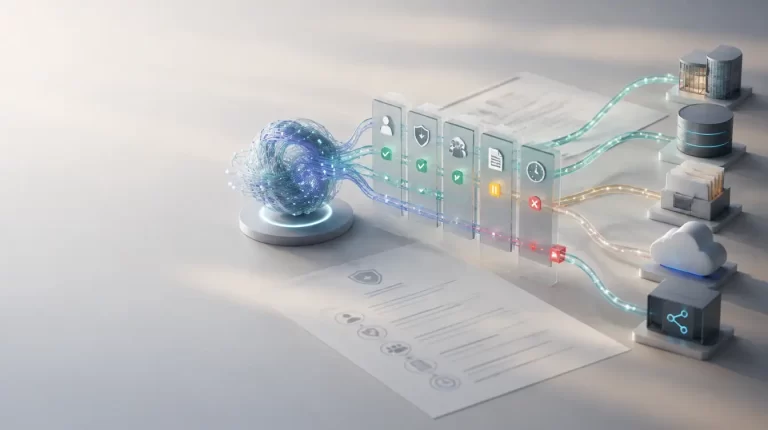
But connecting a model to everything and relying on the prompt to determine what it should see is not an access-control strategy. The system should decide what information the user and the AI are permitted to retrieve before that information is provided as context.
That also means dealing properly with sensitive data. Personally identifiable information, confidential customer information and commercially sensitive data may need to be masked, filtered or kept out of particular models or environments altogether.
This is where private AI becomes practical rather than theoretical. It is not simply about where a model is hosted. It is about knowing where company information is going, what is allowed to leave a controlled environment, and which systems or models are permitted to process it.
An AI tool is also a form of authority
Data access is only half of the problem. Once an AI agent can use tools, the question becomes what it may actually change.
Reading a CRM record has one risk profile. Updating it has another. Creating an invoice, changing user permissions, deploying code, sending a customer communication or initiating a transaction each carries more consequence than the last.
The AI may technically be capable of all of them. That does not mean it should receive unrestricted access to the API behind them.
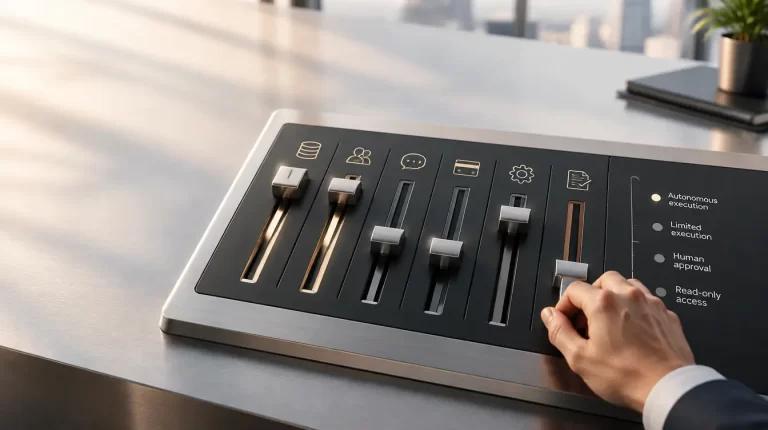
Tool access needs scope. An agent might be permitted to retrieve a customer record but not edit it. Another might prepare an update but require someone to approve it. A low-risk, well-understood workflow may eventually be allowed to execute automatically within defined limits.
This gives organisations a more useful way of thinking about AI agents. You are not choosing between “AI can act” and “AI cannot act”. You are deciding how much authority a particular AI use case receives.
Human approval should depend on consequence
Not every AI action needs a person watching it. That defeats much of the point. But not every action should run autonomously either.
The practical approach is to match human involvement to the consequence of the action. Summarising an internal document might need no approval. Preparing a customer response may need someone to review it before sending. Changing a customer’s financial details should almost certainly require stronger controls.
The important part is that this is decided in advance. The model should not be inventing the approval process as it goes.
NIST’s guidance on generative AI risk management takes a similar approach. It recognises that different AI uses can require different levels of human oversight, tracking and documentation depending on the organisation and the risk involved. That is close to the way IT teams already manage risk: not everything gets the same control.
You also need to know what happened afterwards
If an AI system only generates text, a conversation history may be enough for some use cases. Once AI starts acting across business systems, that changes.
You may need to answer questions like these:
- Who made the original request?
- Which information was retrieved?
- Which permissions were applied?
- Which model processed it?
- What did the model recommend?
- Which tool did it attempt to use?
- Was approval required, and who gave it?
- What action was eventually taken?
If something goes wrong six months later, “the AI did it” is not an audit trail. Businesses need enough traceability to reconstruct the sequence.
This matters most for organisations operating under privacy, security, financial or industry-specific compliance requirements, but I would treat it as good operational practice even where no regulation demands it.
Private AI does not mean cutting yourself off from better models
There is another misconception worth clearing up. Private AI does not mean choosing one model, putting it inside your network and ignoring everything outside it.
Models will keep changing. Astra will not be the last significant release.
An organisation may want one model for a particular reasoning task, another for coding, a local model for highly sensitive workloads and a frontier model for work where its extra capability justifies its use. The architecture should allow that.
What should stay consistent is the organisation’s control over its data, permissions, tools, policies and audit history. Otherwise every new model becomes another security and governance project.
This is the problem we built RebelCore to address
RebelCore gives organisations a private foundation for connecting AI models to business data and systems without handing those models unrestricted access. It lets a business control the path between a user’s request and the eventual outcome.
In practice that means identity- and permission-aware access to approved company data, protection for sensitive information moving in and out of AI workflows, scoped access to tools and APIs, human approval where it’s needed, policy controls, and a traceable record of what happened.
The deployment model can match the sensitivity of the workload. For some organisations that may be a protected Microsoft Azure environment. Other workloads may need private infrastructure or local NVIDIA-powered systems. Highly sensitive environments can be isolated completely. The point is not to force every workload into the most restrictive architecture; it is to let the organisation choose the appropriate boundary.
RebelCore is also model-flexible, which matters because businesses should be able to adopt models such as GPT-6 Astra, or whatever comes after it, without rebuilding their access controls, data connections and governance model each time.
The model can change. Your rules should not disappear with it.
Before giving an AI agent access, answer these questions
More capable AI agents do not require businesses to stop adopting AI. They require more discipline about how it is deployed.
Before connecting an agent to real company systems, I would want clear answers to six questions:
- Who is the user?
- What company information may they access through the AI?
- Which tools and systems may the AI use on their behalf?
- What actions may it perform without approval?
- Which actions require a person to approve them first?
- Can we reconstruct exactly what happened afterwards?
If those answers are vague, the problem is not that the model is too capable. The organisation has not yet defined the environment in which that capability is allowed to operate.
GPT-6 Astra shows where enterprise AI is heading. The models can increasingly do the work. Our job in IT is to make sure they do the right work, with the right information, under the right authority.