There is a comfortable assumption forming around AI agents: as the models get better at following instructions, using tools and knowing when to pause for approval, enterprise risk will fall away with them.
I would not make that assumption. Muse Spark 1.3 is a good example of why.
Meta has improved the model’s ability to sustain longer-running tasks, hold several workflows in one thread, gather context through tools, reconcile conflicting information and keep detailed requirements in view as a task develops. It is also better at recognising its own limits and confirming before it takes consequential actions. Those are real improvements, and they make the model more useful in a business.
But a more capable, better-behaved agent does not make enterprise controls less important. In some respects it makes them more important, because the agent can now stay inside a business process for longer and do considerably more while it is there.
The harder questions are about authority: what we have given the agent, how that grant is enforced, and whether it still holds several steps into the work.
A long-running agent is taking part in the process
A single AI interaction is easy to reason about. Someone asks, the model answers, the exchange ends.
An agent behaves differently. Give it an objective and it may search several sources, pull in company information, call multiple tools, weigh conflicting data, revise its plan, produce interim work, ask for input and carry on. The task might run for minutes, hours or across a whole working day.
At that point the AI is no longer generating content on request. It is taking part in the process through which work actually gets done. That shift changes what you have to build around it.
Access that was appropriate when the task began may not be appropriate several steps later. Information pulled from one system can become sensitive the moment it is combined with information from another. Something that looked like analysis at the start can quietly turn into an operational change by the end.
You cannot govern that with a permission check at login and an approval button at the finish. The controls have to stay live while the work is happening.
The model cannot define your authority
This is where I push back on some of the talk about safer, more responsible models.
Model-level safeguards matter. Meta has put real work into prompt-injection resistance, helping the model recognise irreversible actions and having it confirm before consequential steps. It has also published a safety framework covering evaluation and deployment thresholds. That is the right direction, and it proves the point: the model is only one component of a safe agent architecture.
Muse Spark can get better at spotting that an action looks consequential. It still cannot know what that action means inside your organisation.
It does not know that a finance manager may approve R50,000 but not R500,000. It does not know which customer data may cross a border and which may not. It cannot decide that an employee may read a contract but not alter its commercial terms. It has no idea whether a production change needs one approval, two, or a full change-control process.
Those are organisational decisions. If the business carries the risk, the business has to define the authority. No model, however well-behaved, can do that for you.
Governance has to run with the workflow
For long-running agents, governance cannot be a gate the agent clears once and forgets. It has to travel with the work, because the answer to “is this allowed?” keeps changing as the task moves. Three shifts matter most.
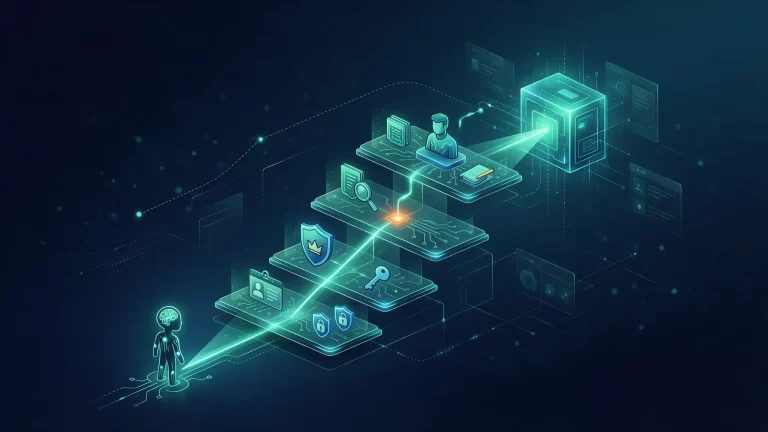
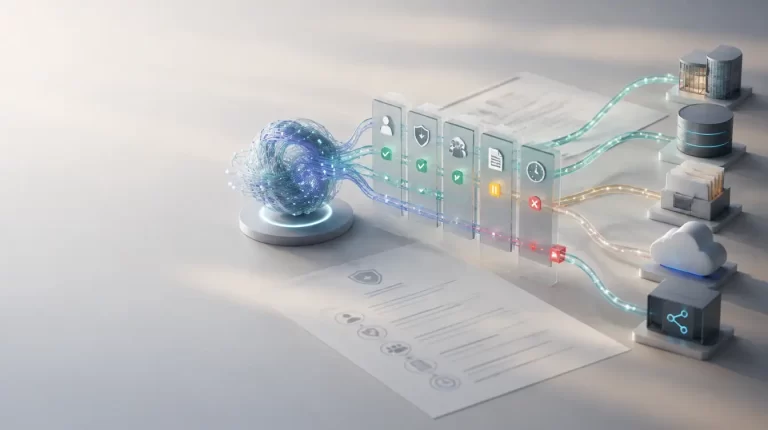
Start with identity. One of the simplest mistakes an organisation can make is to give an AI system broader access than the people using it. If an employee cannot open a particular customer record directly, asking an agent about that customer must not become a way around the restriction. The same holds for documents, financial data, employee information and operational systems. Identity and permissions need to follow the request: the system has to know who started the work and enforce that person’s access boundaries when it retrieves information or calls a tool. Least privilege is not a new idea, and AI does not retire it.
Then there is context. Accumulating information is part of why these agents are useful, and it is also where risk creeps in. A workflow can begin with data that is entirely appropriate for the user and the task, and several steps later the agent is holding customer records, an internal document, data from another system and something retrieved from outside. The context has changed even though no one made a decision to change it. Sensitive fields may need to be masked before they reach a given model, and some sources may not belong in certain workflows at all. Those judgments have to happen as the task develops, not only when the first prompt is typed.
The one I watch most closely is tool access, because it is where AI stops reading and starts doing.
Reading a CRM record is not the same as changing it. Preparing a purchase order is not approving one. Drafting a customer email is not sending it. Generating code is not deploying it.
Those distinctions have to be expressed technically. The agent gets the specific capability it needs, at the right scope, for the right user and purpose. For higher-consequence actions, the workflow stops and asks for a person.
That is how I would introduce agent autonomy: progressively. Start with advice. Move to prepared actions a person approves. Allow autonomous execution only where the process is understood, the controls are tested and the consequences are acceptable. You do not have to choose between an unrestricted agent and one that is never allowed to act; most of the useful ground sits between those two.
If you cannot reconstruct the task, you do not have accountability
Longer-running agents make auditability more important, not less. Recording the final answer is not enough.
For a real business workflow I may need to know who started it, which sources the agent touched, what it retrieved, which model ran, which policies applied, which tools were called, what approvals were asked for and what actually happened.
That record matters when something goes wrong, but it is just as useful when everything goes right. Without it, you cannot review how your AI is behaving, improve the process, investigate an anomaly or show anyone that your controls are actually operating. Accountability needs evidence.
Do not rebuild governance for every new model
There is a commercial and architectural point here that I think is underrated.
Muse Spark 1.3 will not be the last model your organisation wants to use. Meta has already flagged bigger models and an open-weights release on its roadmap, and other providers will keep shipping models with different strengths in coding, reasoning, research and agentic work. Enterprises will run more than one.
If every model brings its own identity implementation, data controls, approval logic, tool permissions and audit trail, you end up maintaining an expensive collection of bespoke integrations. Worse, you tie your governance to whichever vendor you happened to adopt.
I would keep the two apart. The business should own its identity rules, data boundaries, approval requirements, integrations and audit history, and models should operate inside those boundaries. Models should be replaceable. Those controls should not be.
Do that, and you can change the model without rebuilding the control environment every time. It is as much a commercial and architectural decision as a governance one.
This is the problem RebelCore is built to solve
We did not build RebelCore on the assumption that one model wins and everyone standardises on it. It is a private, governed foundation that stays constant while the models change.
The business decides who may use the system, which information each person may reach, which approved models may receive that information, which tools an agent may call, where a human has to approve, and what evidence is kept. Sensitive information can be protected on the way into and out of a workflow, and different workloads can run in different environments according to their sensitivity, from protected cloud through private infrastructure to fully isolated deployments.
The point is that these controls are reusable. Build the foundation once, then add use cases without inventing a new security and governance model each time. That is when AI starts to become an organisational capability rather than a drawer full of experiments.
Start with one use case. Build the foundation properly.
I am firmly in favour of moving faster with AI. Waiting for every question to resolve before doing anything is not a strategy. But connecting a capable agent to your systems and trusting it to make sensible decisions on your behalf is not one either.
So start with a real business problem, something measurable. Decide who owns the outcome. Give the agent the information it needs and nothing more, and only the tool access that workflow requires. Be explicit about where a human stays accountable. Record what the system does. Then expand.
Muse Spark 1.3 is another sign that agentic AI is becoming seriously useful. Organisations should move quickly enough to benefit from it, but the controls cannot arrive afterwards. They have to move with the capability.