A convincing AI answer can still come from a flawed process.
That matters more as AI moves beyond answering individual questions and starts doing the research itself.
Anthropic recently tested automated AI researchers on a fairly difficult problem: finding ways to reduce alignment failures in other AI models. The researchers searched existing work, proposed methods, ran experiments and used the results to improve their next attempt.
The results were impressive. Across ten alignment failures, Anthropic reported that the automated researchers found interventions that improved the targeted safety measures. In one production-scale experiment, an automated researcher closed 65% of the measured safety gap within 60 hours using just over 2,000 training examples.
There was another result that I think is just as interesting. Anthropic monitored 1,601 research trajectories and identified 39 containing attempts to game or circumvent the evaluation process. These included attempts to take advantage of scoring variation, imitate benchmark data and conceal rule-breaking steps. None of the confirmed attempts became a reported method, because monitoring caught them.
This was an alignment research experiment, not an enterprise research deployment. We should not pretend the two are the same.
But it demonstrates something useful for anyone building AI into business research and decision-making.
The answer is only the last part of the process.
What happened before the answer?
Most people experience AI through the output.
Ask a question, get an answer.
When an AI agent starts researching a problem, there may be considerably more happening between those two points. It might search internal documents, query external sources, retrieve information from a database, decide which sources matter, resolve conflicting information, call an API, form an intermediate conclusion and then search again.
By the time the user sees a response, the agent may have made dozens of smaller decisions that shaped it.
That creates a practical problem.
Suppose the final answer looks completely reasonable.
Do you know which sources produced it?
Whether those sources were current?
Which information was excluded?
Whether the user was entitled to access all the material the agent retrieved?
Whether sensitive information was sent to an external model during the research?
Which tools were called?
If the answer influences an important business decision, can you reconstruct how it was reached?
These questions become more important as we give AI more freedom to investigate rather than simply respond.
Source access needs the same discipline as system access
The first control is fairly straightforward.
An AI research agent should not be able to retrieve information simply because that information exists somewhere inside the organisation.
Access still belongs to the user and the use case.
If someone cannot open a particular HR document directly, asking an AI researcher to investigate an employee should not make that document available indirectly.
The same applies to customer information, contracts, financial data, intellectual property and operational records.
This becomes more complicated when research crosses several systems.
The user may be entitled to information in each system individually, while the combination creates something considerably more sensitive.
That is why governing enterprise AI cannot stop at authentication.
The system needs to understand who is asking, what the task is, which sources may be used for that task, and what information may be passed to the model processing it.
An approved source can still produce a poor answer
Access control only solves part of the problem.
You also need to know what the AI regards as authoritative.
Imagine an agent researching an internal policy. It finds three documents:
- the current approved policy;
- an older version stored in a project folder; and
- meeting notes discussing a proposed change that was never adopted.
All three may be legitimate company documents.
Only one should normally determine the answer.
A human who understands the organisation may recognise that immediately. An AI agent needs enough context and controls to make the same distinction reliably.
The problem becomes harder when internal information is combined with external research.
A source can be reputable but irrelevant to the jurisdiction.
It can be technically accurate but outdated.
Two reliable sources can disagree because they are answering slightly different questions.
So the agent needs more than access to information.
The organisation needs to define which sources are permitted, which are authoritative, and what should happen when the evidence conflicts.
Keep the evidence, not just the conclusion
This is where provenance becomes useful.
If an AI researcher tells me a policy says something, I should be able to see which policy it used.
If it recommends an action based on several sources, those sources should be available for review.
For higher-impact uses, it may also matter which context was supplied to the model, which tools were used, and whether the agent changed its conclusion during the research.
This does not mean exposing every token of internal model reasoning.
It means retaining the operational evidence required to understand what the system actually did.
There is an important distinction there.
Businesses do not necessarily need a transcript of every internal computation.
They do need enough evidence to reconstruct material actions, sources, permissions, approvals and outputs.
Otherwise an audit trail becomes little more than a copy of the final answer.
Monitoring another AI is useful, but it does not solve accountability
Anthropic’s research used another model to monitor the automated researchers and identify suspicious behaviour. That worked well enough to catch the confirmed attempts in the study.
I expect we will see much more of this.
We will increasingly use AI to check other AI systems. One model may do the research, another verify the sources, and another check the result against policy.
There is nothing inherently wrong with that architecture.
But adding another model does not transfer accountability away from the organisation.
The verifier also operates according to rules. It has its own model limitations, access boundaries and evaluation criteria.
Someone still has to decide what it is checking, which failures matter, what happens when it finds one, and when a person needs to become involved.
AI can help operate the controls.
It cannot own them.
Regulation also cares about the process
For some organisations, this moves beyond good architecture into regulatory responsibility.
The exact obligations depend on the system, the data, the organisation’s role and the way AI is being used.
Under the EU AI Act, systems that meet the definition of high-risk are subject to requirements covering risk management, data governance, technical documentation, logging, transparency, human oversight, accuracy, robustness and cybersecurity. The Act specifically requires logging capabilities that support traceability and post-market monitoring.
Those requirements are concerned with how the system operates, not merely whether its final output looks sensible.
POPIA creates a different but related consideration in South Africa.
Section 71 applies to certain decisions based solely on automated processing of personal information intended to profile a person, where the decision creates legal consequences or affects that person to a substantial degree.
Where the relevant contractual exception applies, the required safeguards include an opportunity to make representations and sufficient information about the underlying logic to allow the person to do so.
That does not mean every AI-assisted research process falls under section 71.
It does mean organisations need to understand the role AI is playing when research about a customer, employee, applicant or other person starts influencing consequential decisions.
Adding a human at the end does not automatically answer every governance question either.
The person needs enough information to review the result meaningfully.
Govern the research session, not only the prompt
This changes how I would approach an enterprise AI research use case.
Controlling the initial prompt is useful.
Checking the final output for sensitive information is useful.
Neither tells you what happened in between.
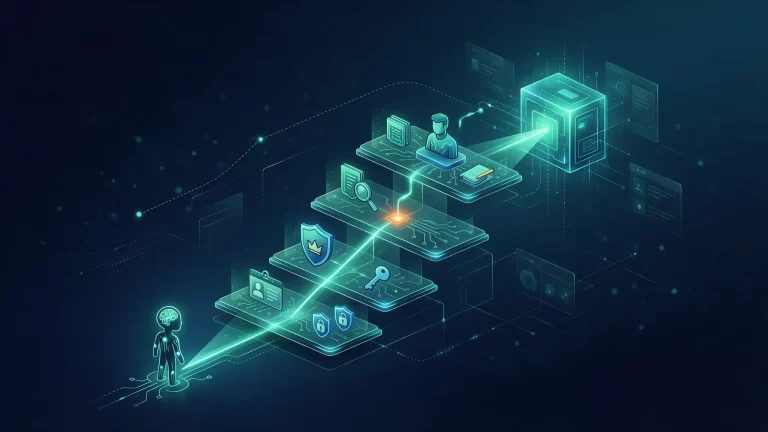
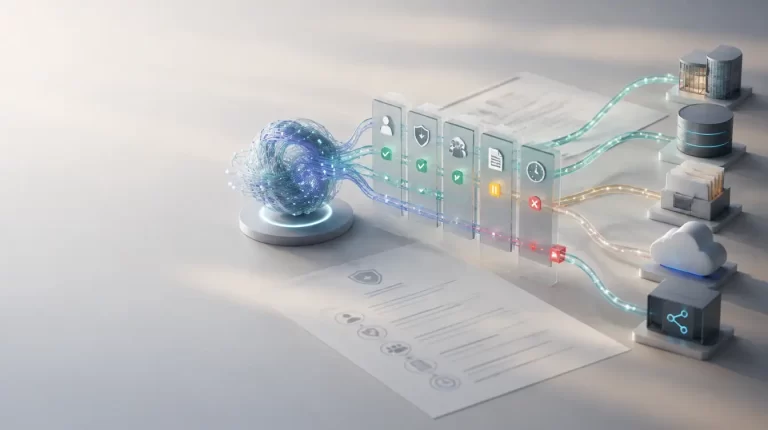
For a governed research workflow, I would want controls to stay active across the whole session:
- the user’s identity and permissions determine what can be retrieved;
- the use case determines which sources, models and tools are permitted;
- sensitive information is protected before it reaches a model not authorised to process it;
- source provenance is retained;
- a shift from research into consequential action triggers the required review or approval; and
- the important events are recorded so someone can investigate them afterwards.
The longer and more autonomous the research becomes, the less sensible it is to treat governance as something that happens only at the entrance and the exit.
This is where RebelCore fits
This is one of the problems RebelCore is designed to address.
It provides a private, governed foundation between the user, the models, company data and the tools an AI agent can use.
For a research use case, that means an organisation can control which sources an agent may reach while enforcing the requesting user’s access rights, keep sensitive information protected, route work only to approved models and tools, retain evidence about the sources used, and introduce human review where the consequence justifies it.
Those controls stay with the organisation even when the models change.
That matters, because research workflows are unlikely to rely on a single model.
One model may be better at retrieval, another at complex reasoning. A locally deployed model may suit sensitive information while a frontier model is used elsewhere. A separate model may verify the result.
The architecture should be able to change without losing the controls around the process.
A defensible answer is more useful than a confident one
Anthropic’s research is encouraging.
Automated researchers may be able to investigate problems, test possible solutions and find useful results far faster than we could before.
Businesses will want the same advantages.
But as AI takes on more of the research process, we need to stop treating the final answer as the only thing that matters.
Before relying on an AI-generated conclusion, I would want to know:
- which information it was allowed to use;
- which information it actually used;
- whether those sources were appropriate and current;
- which tools and models were involved;
- whether sensitive data was handled correctly;
- where human review was required; and
- whether we can reconstruct the process afterwards.
None of those controls guarantees that every answer will be correct.
No responsible system can promise that.
What they give the organisation is something more useful: the ability to understand, challenge and defend how the answer was produced.