Most conversations I have with leadership teams about AI agents eventually arrive at the same reassurance: if it goes wrong, we’ll switch it off. It’s a sensible instinct, and every system that can take consequential action should have that option. The difficulty is that by the time switching everything off is your only reasonable move, you’ve usually already lost more control than you’d like.
Production systems also rarely fail that neatly. More often, one part of a workflow starts drifting while everything around it carries on working perfectly well; a connector returns something unexpected, a CRM field changes, someone lands in the wrong access group, or a model update shifts behaviour under one particular instruction. None of those, on its own, justifies shutting down every AI service in the business, but equally none of them is something you’d want to leave running while you investigate.
We already handle this well elsewhere in technology. When a user account looks compromised, we disable that account; nobody switches off Microsoft 365 for the whole company. When a payment channel behaves oddly, we lower its limits or block the route. What I’d want for AI agents is the same kind of graduated control, and that’s essentially what I mean by an emergency brake: a way to take authority away from an agent quickly and precisely, without necessarily stopping it.
Capability and authority are different things
The question I’d put to any team deploying an agent is less about what the model can do and more about what it is currently authorised to do. A capable model can change a customer record, issue a refund, send a message or trigger a workflow; that capability tells you very little about whether it should be allowed to do any of those things today, in this workflow, for this user.
Authority is something the organisation grants, which means the organisation should be able to adjust it while the system is running. That matters because risk moves. A use case that has run reliably for six months can meet a new data source, a new model version, a changed integration or a new regulatory requirement, and the business needs to be able to redraw the boundaries without redesigning the application.
Levels of autonomy, in both directions
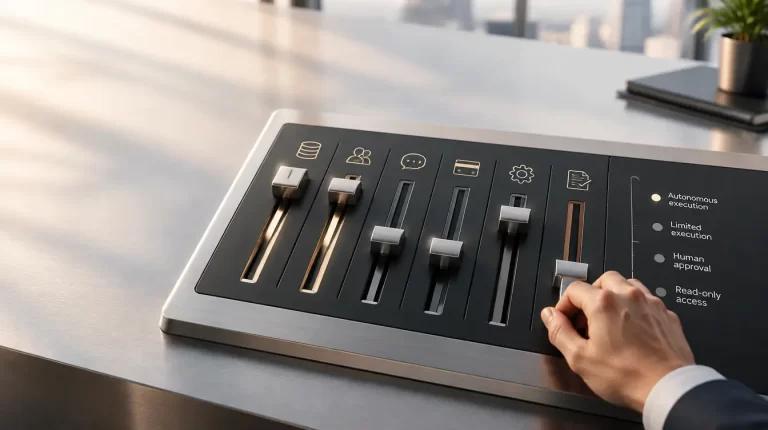
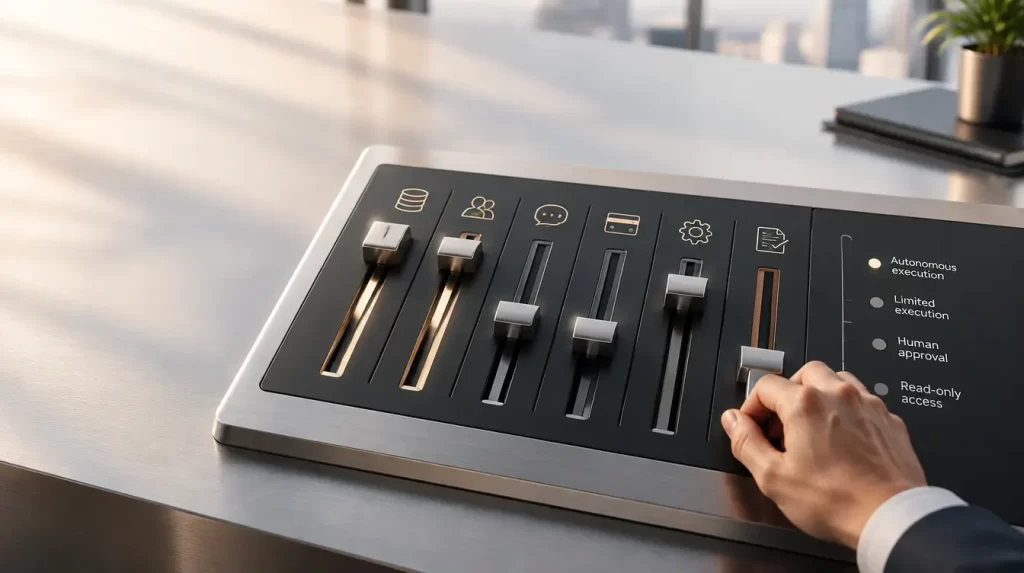
I find it more useful to think about agents in levels than as simply autonomous or not. At the lowest level the agent reads and advises: it retrieves authorised information and makes a recommendation, but changes nothing. Above that it prepares actions, populating the form, drafting the message or staging the system change, while a person approves execution. Then comes limited execution within explicit thresholds and, for mature and predictable workflows, broader autonomy inside boundaries you’ve defined.
The part that tends to get missed is that movement between these levels has to work both ways. If something changes, you should be able to take an autonomous workflow and put it straight back into approval mode, and keep it there while the team works out what happened.
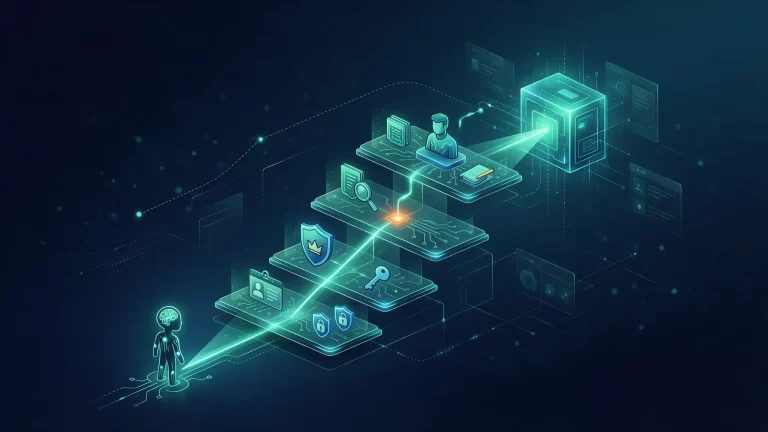
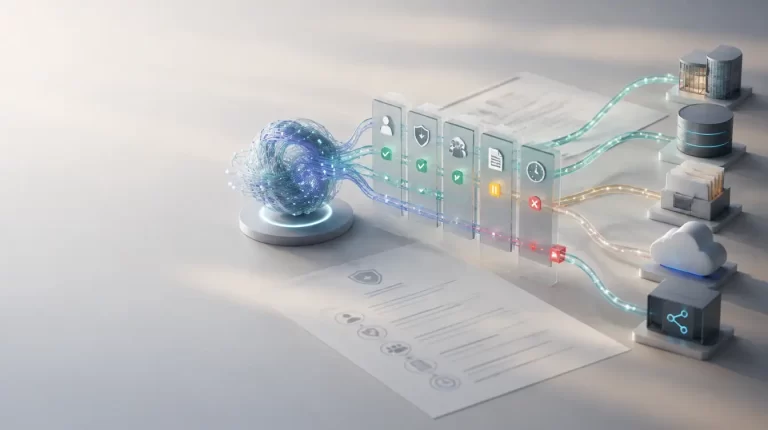
That only works if permissions are granular enough to adjust. “The agent can use the CRM” isn’t really a permission at all; searching customers, reading contact details, seeing payment history, changing an address, applying a credit and exporting the database are each different capabilities with very different consequences. The safest architecture exposes only the capabilities a use case genuinely needs, so that when something shifts you can restrict one of them, disable a single API or cut off one data source, and leave the rest of the workflow running.
Approval that tightens and relaxes with risk
Human-in-the-loop is often treated as a design decision you make once and then live with. I’d argue it should behave more like a setting that responds to risk.
Take an agent authorised to process routine refunds under R500 automatically. It may run cleanly for months, and then monitoring picks up something unusual. You don’t need to switch the service off; you change the policy so that every refund needs approval. The agent keeps doing the useful, lower-risk work of pulling the customer history, checking the transaction and preparing the refund, and simply loses the authority to complete that last consequential step. Once the issue is understood and fixed, the business can decide, deliberately, whether to restore the earlier autonomy.
Seeing the problem, and knowing who acts on it
None of this is possible if you can’t see what the agent is doing, and monitoring model availability isn’t enough. I’d want to know which tools are being called and which data sources accessed, whether approval or override rates are moving, whether action volumes have drifted outside their normal range, and whether a new model version has changed behaviour. Without that telemetry, reducing authority becomes guesswork, and people tend either to overreact or to wait too long.
The other question that gets overlooked is who is allowed to pull the brake. It can’t simply default to whoever has administrator access. Someone needs clear authority to suspend an integration, force a workflow back into approval mode, or block a model or data source, and the people around them need to understand when those controls are expected to be used. Depending on the organisation that may involve IT, security, risk, compliance and the business owner of the use case; the exact structure matters less than having it agreed before there’s an incident, because a control nobody feels entitled to use doesn’t offer much protection.
Fail toward less authority
If I had to pick one architectural principle from all of this, it would be that when something important becomes uncertain, the system should move toward less authority. If identity can’t be confirmed, access narrows. If a data source can’t be trusted, the agent stops using it. If a high-impact action can’t get its required approval, it doesn’t happen; and if an approved model becomes unavailable, sensitive work shouldn’t quietly reroute to one that hasn’t been approved.
This isn’t an argument for shutting things down at the first error. A well-designed system has several lower-authority states it can step down into long before a full stop becomes necessary, and that’s what keeps it useful while a problem is being investigated.
It also can’t be added afterwards with a policy document. The controls have to live in the architecture, and they need to be shared across use cases; if every agent implements its own access control, approval logic and logging, you end up with a collection of systems that each behave differently under pressure, which is hard to run and harder to govern. That’s a large part of why we built RebelCore around governed permissions, controlled integrations, human approval and traceability. An organisation can decide which data an agent reaches, which tools it uses, what it may do, what needs sign-off and which models are permitted, and keep that foundation consistent as the use cases change around it.
Before you hand over authority
We want agents to take on more useful work; that’s the whole reason for deploying them. The more authority we give them, though, the more precisely we need to be able to take it back. Before I let an agent act inside a business, I’d want the team to answer three things with confidence: can we reduce what it’s allowed to do without switching off the whole use case, can we see what changed before a problem appeared, and do we know who is responsible for stepping in?
The kill switch still belongs in that picture, and there will be moments when stopping everything is exactly the right call. It just shouldn’t be the only control you have.