What happens to your business when the AI isn’t there? Not when the model gets an answer wrong, but when the service is simply unavailable. The provider’s API is down. A cloud region has an outage. Authentication fails. A system the agent depends on stops responding.
If the honest answer is that people wait until it comes back, then you haven’t just added AI to a workflow. You’ve added a new business dependency. The question is whether you’ve designed the business to survive when that dependency disappears.
AI is moving from useful tool to operational infrastructure
That shift happens faster than most organisations notice. A business starts by using AI to summarise documents. Then it connects the model to the CRM. Before long it is classifying enquiries, preparing quotes, extracting contract data and routing customer requests.
Each step makes the AI more valuable, and each step raises the cost of an outage. When a writing assistant stops working, productivity dips. When the system processing incoming customer requests stops working, the process stops with it.
Those are different categories of risk, and the move from one to the other is rarely a deliberate decision. It should be.
Start with the business service, not the AI platform
Resilience conversations tend to get technical too quickly. The first question isn’t how to build redundant AI infrastructure. It’s which business process you’re protecting, and how much disruption that process can tolerate. The thing you’re protecting isn’t the AI. It’s the business service the AI supports.
That’s why I like the operational-resilience framing used by the Bank of England. Firms are asked to identify their important business services and set an impact tolerance for each: the maximum disruption a service can absorb before customers or the business are harmed. Resilience is measured by what happens to the service, not by whether a server is running, and that framing applies well beyond financial services.
Regulators are already rehearsing this failure
On 8 October 2026, the UK’s Cross-Market Operational Resilience Group, chaired by the Bank of England and UK Finance, ran SIMEX26. The sector-wide exercise involved 38 of the country’s largest and most systemically important banks and market-infrastructure operators. The scenario was a global disruption to cloud-based services. Bank of England SIMEX26 release
The concern isn’t limited to cloud outages. In June, the Bank of England said it was considering whether banks need “enhanced recovery” for core systems as agentic AI spreads through financial services. This week, Reuters reported that banking supervisors are stepping up their scrutiny of AI, pressing banks on agentic systems, cyber risk and whether their recovery arrangements would hold when important technology fails. The pressure is arriving through supervision rather than a new rulebook, which means the questions are being asked before the rules are written.
South African regulators are watching the same underlying risks. The Prudential Authority’s latest annual report highlights operational resilience and third-party concentration, and SARB consulted in 2025 on cloud computing and data offshoring in the national payment system.
These are financial-services examples, not rules for every manufacturer, retailer or professional-services firm. But the principle travels well: outsourcing infrastructure does not outsource the consequence of its failure. Your customers still call. Your production line still needs information. Your contracts still apply.
Match resilience to the consequence of failure
Two positions come up repeatedly, and both are wrong. One says the provider’s uptime is excellent, so rely on it. The other says every AI workload needs duplicate infrastructure. The right level depends on what breaks.
In practice, three tiers cover most cases:
- Low-impact workloads such as research assistants and drafting tools can accept provider recovery. Record the dependency as an accepted risk and move on.
- Core operational processes such as customer intake, quoting and document processing need a manual fallback, safe queuing of work and an underlying software path that continues without the AI layer.
- Critical services such as payments, fraud controls and production systems need independent recovery. That means an alternative model or service for essential functions and, for sensitive workloads, private or locally controlled infrastructure.
If you can’t say which tier a workflow belongs in, that’s the first gap to close.
Design the business at 60% capability
The question I’d put to any organisation moving AI into a core workflow is what the process looks like at 60% capability. Not zero. Sixty.
A usable degraded mode has a few clear properties. Staff can still reach the underlying information without the AI layer. Transactions can be handled manually, in priority order, while lower-impact work is deliberately delayed. Incoming work queues with a timestamp rather than disappearing. And everyone knows, without guessing, that the business is now operating in fallback mode.
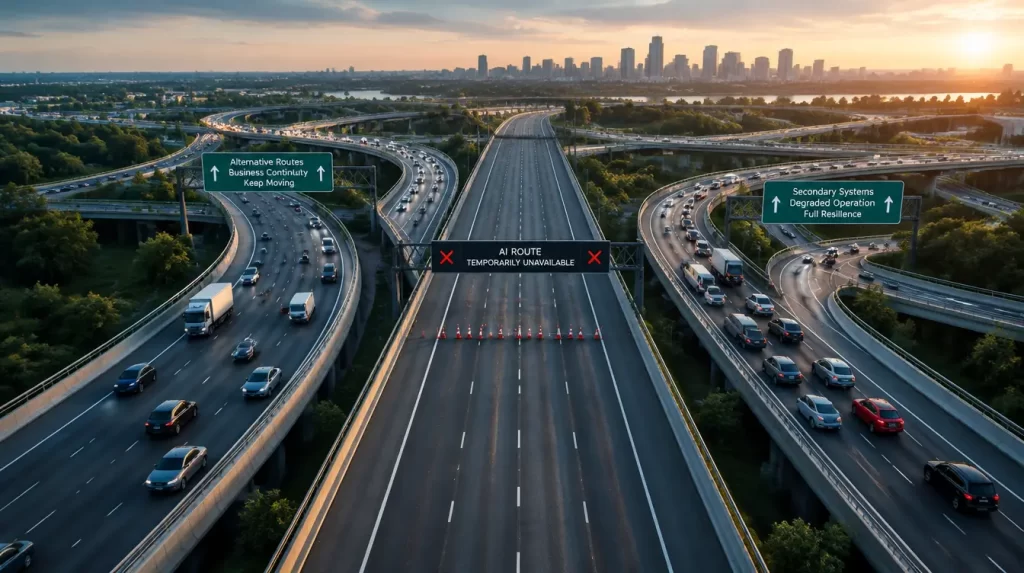
Consider a hypothetical insurer whose claims-intake agent goes down on the last working day of the month. At zero, claims bounce or vanish and the call centre fills up. At sixty, new claims land in a queue, urgent claims are flagged for manual capture and customers are told their claim has been received. When the agent returns, it resumes processing the queue without resubmitting anything already handled. Same outage. Very different day.
That’s what a continuity plan looks like. It isn’t a second server waiting somewhere. It’s a deliberately designed way for the business to keep operating at an acceptable level.
Someone has to own the switch to fallback
Degraded mode only works if someone has the authority to declare it, and that authority needs to be explicit. Name who decides the business has moved into fallback, what triggers that decision and who decides that normal operation can safely resume.
The decision should also be recorded. When the service recovers, you need evidence of when fallback started, what was processed manually, what was queued and what the system replayed. Without that record, reconciliation becomes guesswork and the post-incident review becomes a matter of opinion. For regulated businesses, it is also the evidence a supervisor or auditor will ask for.
This is where resilience and governance become the same discipline. Ownership, approvals, logging and auditability aren’t paperwork for the compliance file. They’re what make a fallback trustworthy.
Agents carry dependencies the AI label hides
Agents make resilience harder because the model is often not the most fragile part of the workflow. A single agent might depend on a model provider, cloud hosting, an identity service, a vector database, internal APIs, third-party SaaS platforms, document repositories and network connectivity, along with whatever those systems depend on.
A second model isn’t a fallback if it fails for exactly the same reason as the first. If both models depend on the same authentication provider, cloud region, network or source system, you’ve duplicated the model without removing the dependency. Resilience planning has to map the real workflow end to end, not simply duplicate the component labelled “AI”.
Recovery needs the same attention as failure. An agent that reconnects halfway through a task and blindly repeats its previous actions can submit a payment twice, create duplicate records or send the same customer three emails. Actions need to be idempotent, meaning safe to retry without producing the same outcome twice. At minimum, they need to be traceable enough that the system can tell exactly what completed before the outage.
Test failure before production tests it for you
You don’t find out whether a continuity plan works by reading it. You find out by breaking something deliberately while the stakes are low. Take the model offline. Disable an API. Remove access to a document repository. Make the authentication provider unavailable.
Then watch the business process, not the dashboard. Work should queue safely. Staff should continue in fallback without needing to ask what to do. Customers should be told what is happening. Recovery should complete without duplicated actions or unclear transaction states. Wherever one of those fails, you’ve found work to do.
The UK financial sector rehearses cloud failure at scale because resilience has to be exercised, not assumed. You don’t need to be a bank to borrow the habit.
AI should strengthen the business, not become a single point of failure
At GoRebel, the architecture decision usually comes before the AI decision. For some workloads, a cloud service with a documented fallback is enough. For others, private or air-gapped deployment is the right answer. In some cases, the business needs a controlled way to use different models so that one provider’s outage doesn’t stop essential work.
That’s part of the thinking behind RebelCore: a controlled foundation for models, permissions, integrations and oversight. But the platform is only one part of resilience. No technology removes the need to design the underlying business process to fail safely. Sometimes the most important design choice has nothing to do with AI at all. It’s making sure the process can still operate without it.
No serious technology strategy should rest on the assumption that AI will always be available. The better goal is knowing exactly what the business does when it isn’t.
Before you move the next AI workflow into production, switch it off on paper. If the business stops with it, you’ve found an architecture problem worth solving before launch.
This article provides general technology, operational-risk and governance information and should not be treated as legal advice.