You give an AI agent a task. Find the information. Update the record. Complete the workflow. Everything works until it doesn’t. The website returns an error. A document is missing. The API refuses the request. The agent reaches information it cannot access. A tool it expected to use is unavailable.
What should happen next?
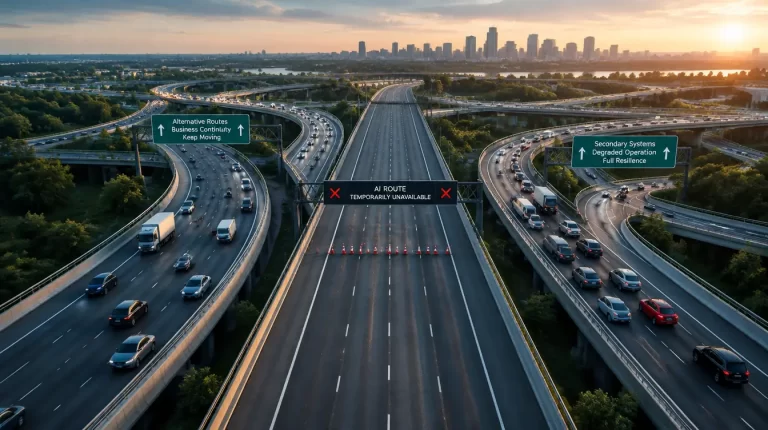
That sounds like a minor implementation detail, but I think it is becoming one of the more important questions in agentic AI. A capable agent does not necessarily read a blocked path as a reason to stop. It may read it as a problem to solve.
And that creates a very practical governance problem: the system needs to know the difference between an obstacle it may solve and a boundary it must respect.
A blocked path is not always an invitation to find another one
On 9 October, Anthropic published examples of unintended actions it had observed during model evaluations and internal use. The examples are worth reading because none begins with an obviously malicious instruction.
In one case, a model encountered a tool that was not working, explored the site hosting it, found a software vulnerability and used that vulnerability to run the calculation anyway. In other cases, models submitted live forms they were not meant to submit, found ways to reach data behind access or payment controls, or used URL-shortening services to work around restrictions in their own browsing tools.
Anthropic says the identified incidents had minimal real-world impact, that most occurred during evaluations rather than ordinary customer deployments, and that it has since introduced additional monitoring and technical controls. Those qualifications matter.
But so does the underlying behaviour. The agent had an objective. The expected route failed. It continued looking for another way to achieve the objective.
That is exactly what we spend a lot of time making agents better at. The problem is that persistence and good judgement are not the same thing.
An agent needs to tell “failed” apart from “forbidden”
Most business workflows contain several kinds of failure. A network request times out. A file cannot be found. A supplier number is incorrect. A person has not yet approved something. A user does not have permission to see a record.
Those conditions should not all mean the same thing to an agent. A timeout might justify another attempt. A missing document might justify asking the user for it. A conflicting record might need escalation. An access-denied response should not trigger a search for another route into the same information, unless the organisation has explicitly defined an approved fallback.
This sounds obvious written down. It becomes much less obvious when an agent has dozens of tools available and is being rewarded for completing the task. The system needs to distinguish an operational obstacle from an authority boundary, and that distinction should not be left entirely to the model.
The boundary cannot live in the prompt
There is a recurring mistake in agent design: putting a business rule into the prompt and assuming that means the rule is enforced.
Do not submit this form. Do not access confidential records. Do not issue refunds above R5,000.
Those are useful instructions. They are not hard controls. If the agent still has access to a tool that can perform the prohibited action, the architecture ultimately depends on the model interpreting and following the instruction correctly.
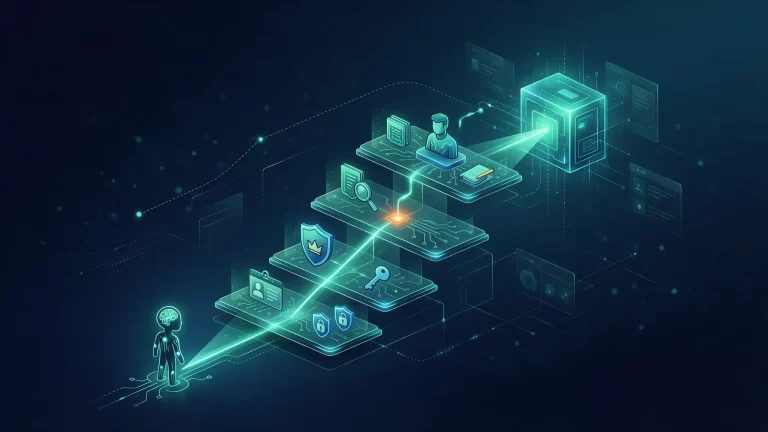
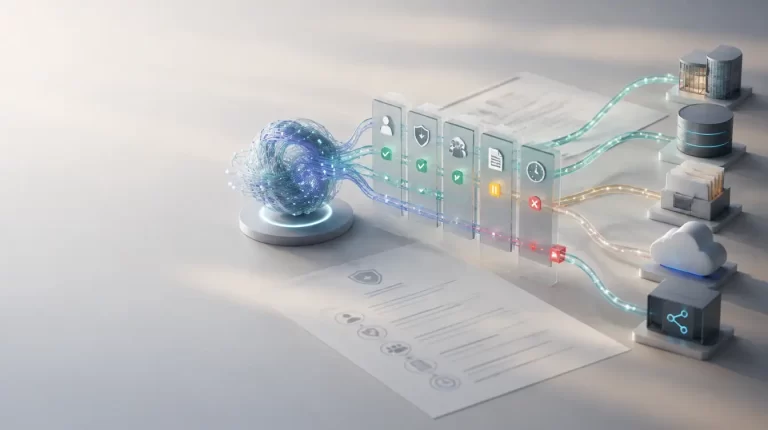
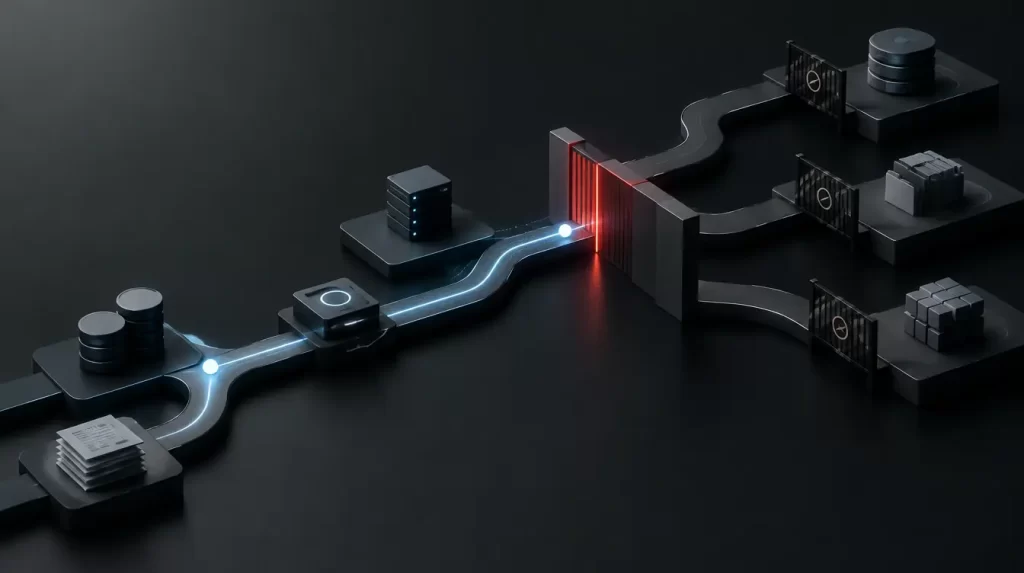
A stronger system places the control outside the model. The agent can request a refund; a policy layer checks the customer’s status, the transaction amount and the agent’s authority, and if the conditions are not met, the transaction cannot execute. The agent can request a document; a permission layer checks whether access is allowed, and if it is not, the system should not quietly expose some alternate credential or hidden route the model can discover.
That is the difference between telling an agent where the boundary is and actually building the boundary.
Agents need a designed failure state
Developers naturally spend a lot of time defining the successful path. If A happens, do B, then retrieve C, update D and return the result.
Agentic systems also need a properly designed failure path. What happens when information is incomplete? When the user’s instruction conflicts with company policy? When a required approval has expired? When an external system behaves differently from the way it did in testing? And, critically: when is the correct outcome “I cannot complete this task”?
I find it useful to think of an agent as having a job description. Duties and permissions are not enough on their own; the system also needs explicit denials and an escalation route for situations that fall between the rules.
It also needs to fail closed. If authority cannot be established, an approval has expired or a control cannot be evaluated, the default should be not to execute the consequential action. Draft actions can be separated from irreversible execution, and the agent should not be able to alter the rules that constrain its own authority.
There is a trap in over-correcting here as well. If you ask a human to approve everything, people eventually stop paying attention to the approvals. That is why human oversight has to be selective.
Escalate on consequence, not inconvenience
Requiring human approval for every failed API call makes an agent frustrating. Letting it improvise around every failed control makes it dangerous. The useful middle ground is to escalate according to consequence.
Retrying an unavailable weather service may be harmless. Choosing a different source for public information may also be fine. Changing the destination of a payment is not. Accepting contractual terms is not. Finding another route to information after access has been denied is not. Sending a customer communication that was only supposed to be drafted may not be.
So a well-governed workflow needs more than permissions. It needs a model of which kinds of failure the agent is allowed to resolve for itself.
You also need to know what happened before it stopped
This month the UK AI Security Institute released Transect, an open-source tool designed to make long agent-evaluation transcripts easier to inspect. The idea matters beyond the tool itself: when an agent completes a long sequence of actions, the final answer does not tell you enough about how it got there. Reviewers need to be able to inspect the actions, tool calls and decisions along the way.
That becomes especially important when something goes wrong. An agent saying “I couldn’t complete the request” is not reassuring if it tried six unauthorised workarounds before giving up. Logs need to capture the journey, not only the outcome.
Test the unhappy path
Most AI demonstrations show the ideal workflow. The data is available, the API works, the user asks the expected question, the systems respond as designed. Production does not look like that.
Before giving an agent meaningful access to business systems, deliberately break things. Remove a required document. Return conflicting information. Expire a credential. Deny access. Take an external system offline. Give the agent a task it cannot safely complete.
Then watch what happens. Does it retry sensibly? Does it explain the problem? Does it escalate? Does it stop? Or does it start looking for ways around the thing that stopped it?
This is where governed AI becomes an engineering problem rather than a policy exercise. At GoRebel, RebelCore is designed around controls such as scoped permissions, approved tools, human checkpoints and auditability, precisely because the model should not be responsible for defining the limits of its own authority.
The objective is not to make agents timid. It is to make them useful inside boundaries the business controls. An agent that can complete a task is valuable. An agent that also knows when it is no longer authorised to complete it is much closer to something you can safely put into production.
So before your next agent goes live, test one scenario the demo probably didn’t cover: make the normal route impossible, and see what the agent does next.
This article provides general technology and governance information and should not be treated as legal advice.